bun-packrat is a self-hosted archive for rendered web pages, designed as a compact successor to a large ArchiveBox deployment. Each fresh capture stores canonical Chromium MHTML in SQLite alongside its metadata, tags, job history and FTS5 search index.
Full-page HTML, simplified articles, Markdown, EPUB and PDF are derived from the stored snapshot when requested instead of being retained as duplicate files. The service runs on Bun with no external queue, database or search daemon.
Capture requests arrive through the server-rendered web interface, HTTP API, bookmarklet or Bun CLI. The server normalises each URL, applies SSRF checks and records a job in SQLite. An in-process worker opens an isolated Chromium context through Playwright, applies a bounded readiness wait, materialises lazy content and stores the resulting MHTML, SHA-256 hash and derived Readability metadata in one transaction.
Reader routes decode the canonical snapshot into sanitised standalone HTML with captured resources embedded locally. Full-page and Article views use a restrictive Content Security Policy and make no external requests. FTS5 supplies search and filtering, while the same stored capture can produce Markdown ZIP, EPUB 3 and PDF exports on demand.
Captures, canonical MHTML, metadata, tags, queue state and search indexes live in one SQLite database that supports consistent online backup and integrity verification.
Playwright drives Chromium to render pages, dismiss known overlays, reveal lazy content and serialise the final DOM and loaded resources as MHTML.
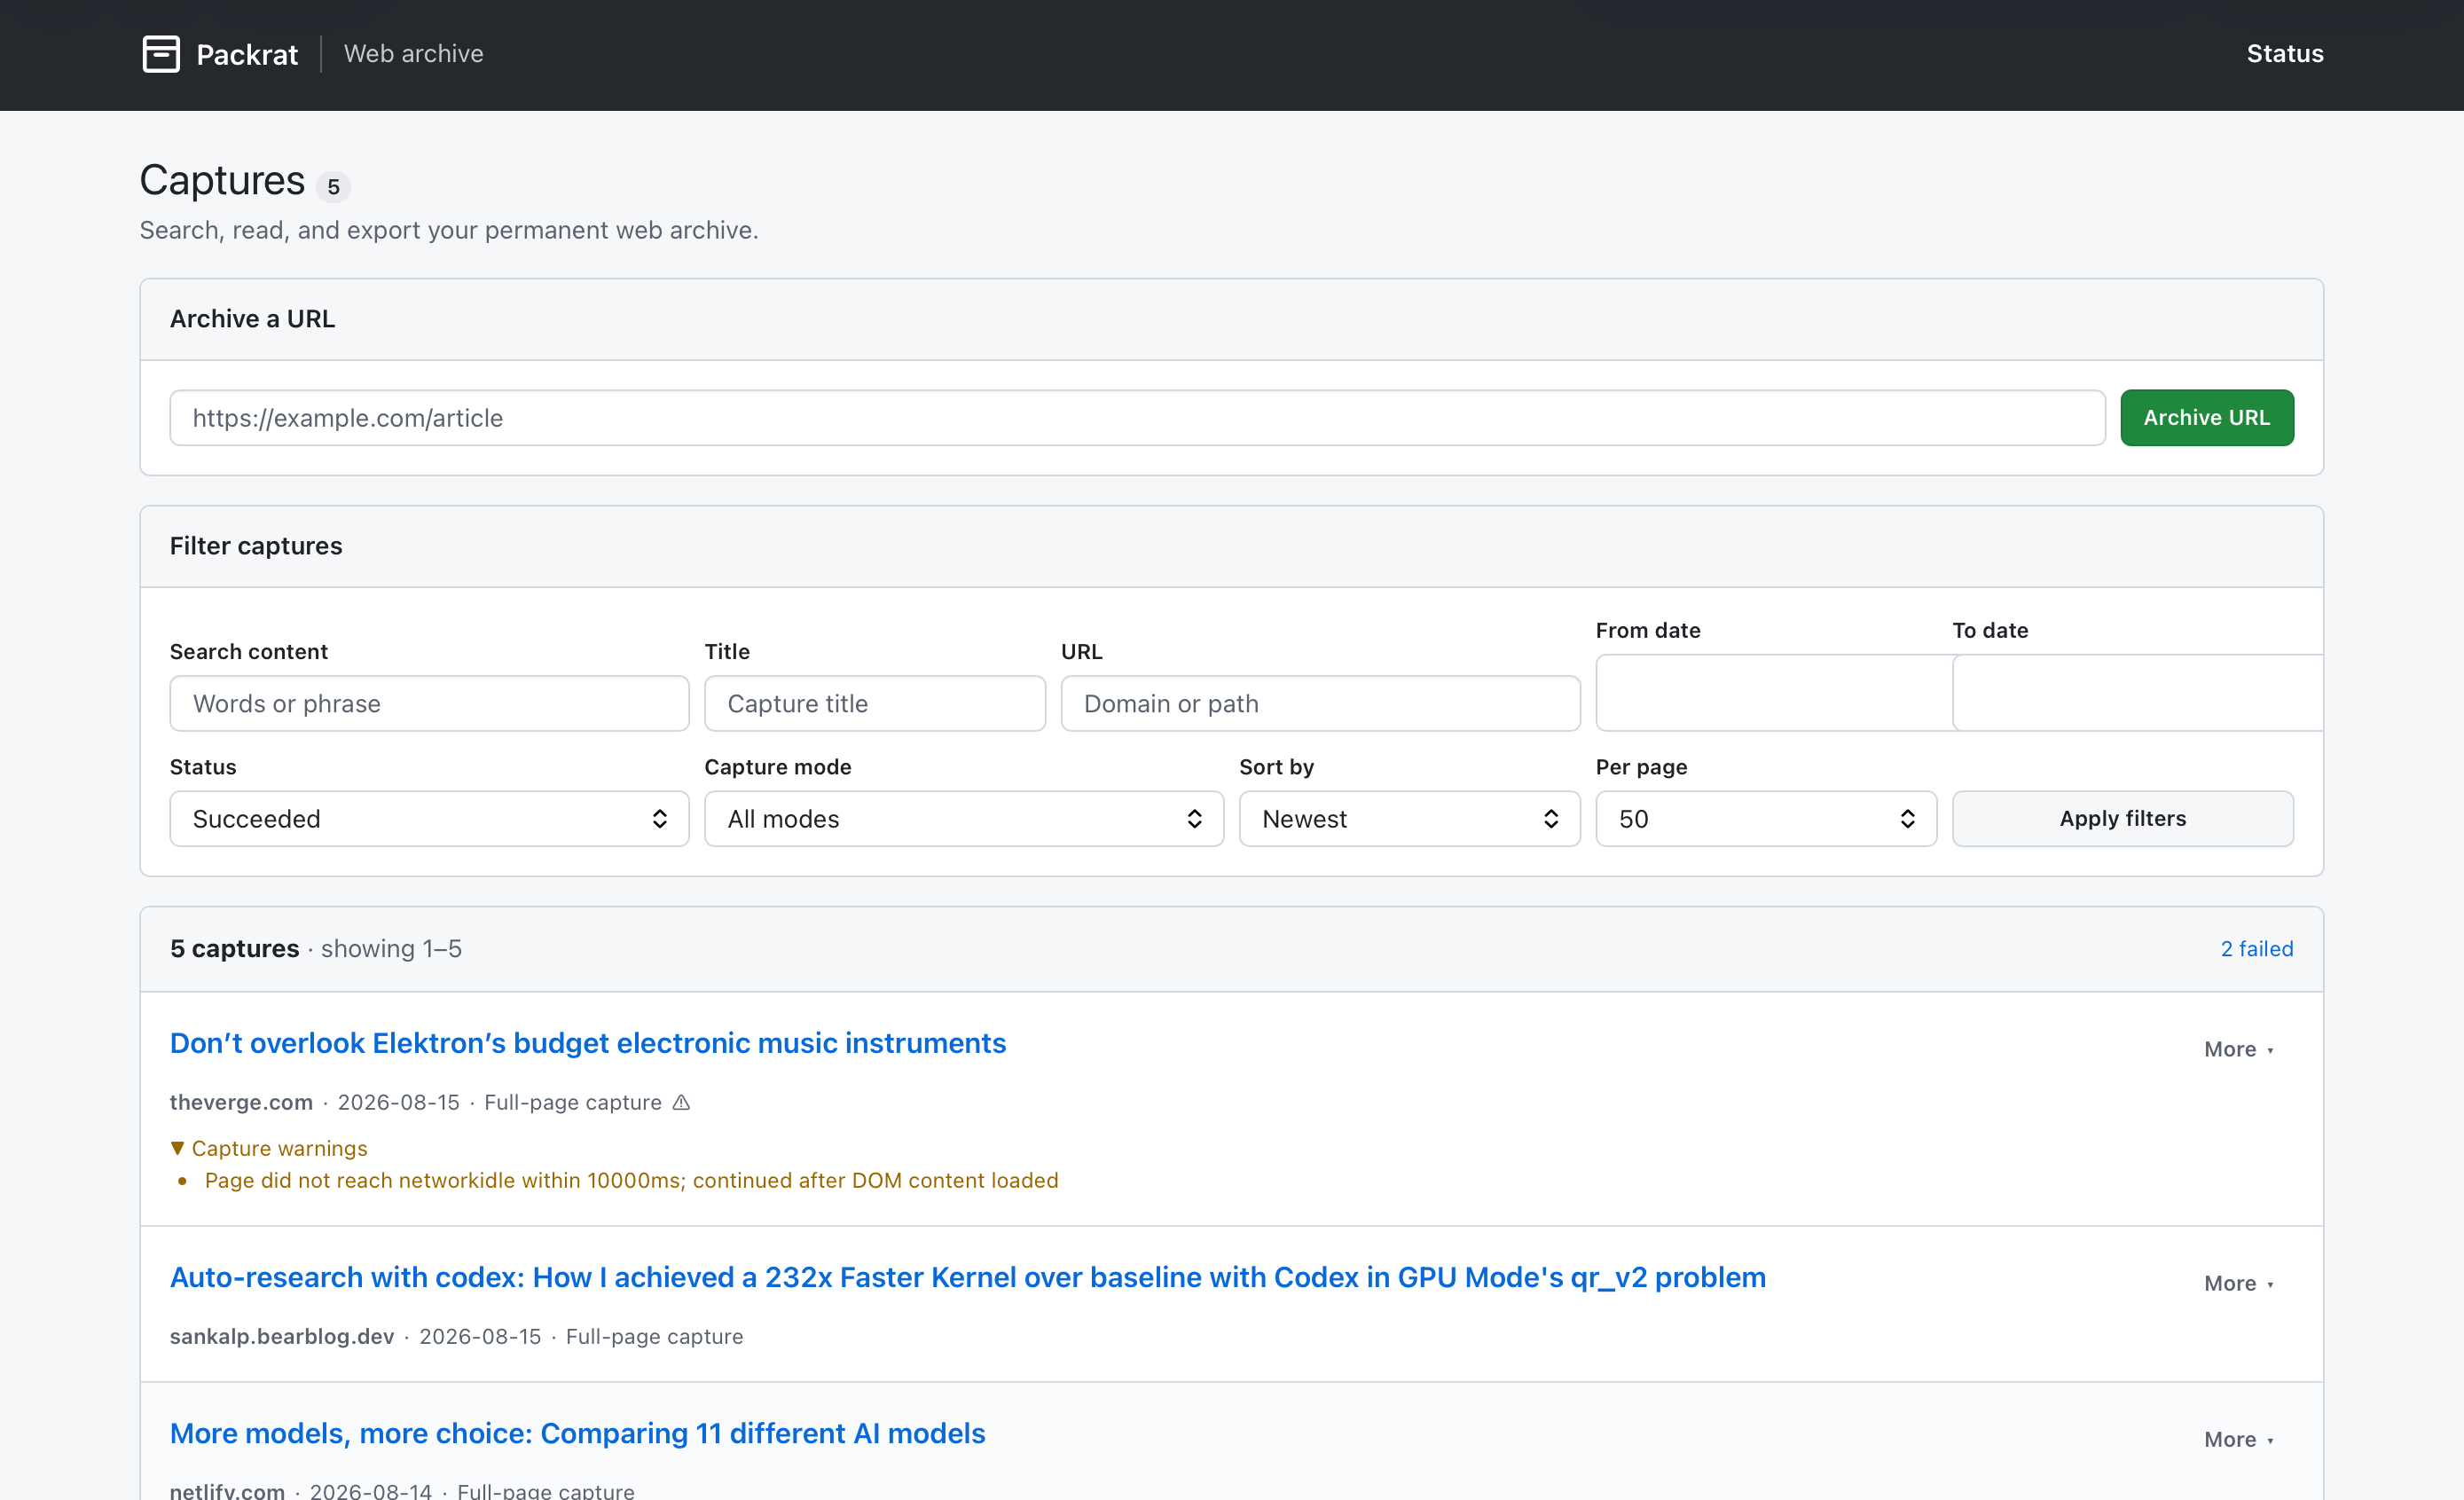
The server-rendered interface and HTTP API provide FTS5 search, filters, deterministic sorting, capture history and paginated results that work on desktop and mobile browsers.
Safe full-page HTML preserves captured styling and media, while a separate Article view uses Readability to produce a responsive, simplified document with embedded images.
Each successful capture can be downloaded as standalone HTML, offline Markdown ZIP, EPUB 3 or an on-demand PDF without maintaining a permanent export cache.
Authenticated HTTP routes and a Bun CLI cover capture, search, export, deletion, status, backup and content-hash verification. Basic authentication is enabled by default.